doctr.datasets#
doctr.datasets#
- class FUNSD(
- train=True,
- use_polygons=False,
- recognition_task=False,
- detection_task=False,
- **kwargs,
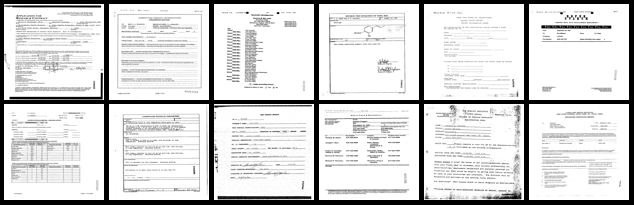
FUNSD dataset from “FUNSD: A Dataset for Form Understanding in Noisy Scanned Documents”.
>>> from doctr.datasets import FUNSD
>>> train_set = FUNSD(train=True, download=True)
>>> sample = train_set[0]
>>> img, target = sample.image, sample.target
- Parameters:
train (bool) – whether the subset should be the training one
use_polygons (bool) – whether polygons should be considered as rotated bounding box (instead of straight ones)
recognition_task (bool) – whether the dataset should be used for recognition task
detection_task (bool) – whether the dataset should be used for detection task
**kwargs (Any) – keyword arguments from VisionDataset.
- class SROIE(
- train=True,
- use_polygons=False,
- recognition_task=False,
- detection_task=False,
- **kwargs,
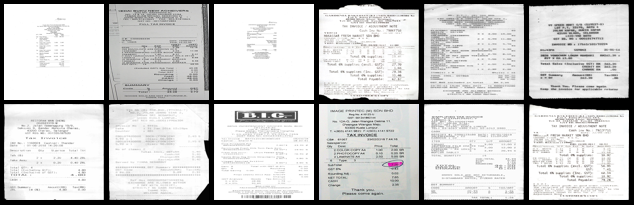
SROIE dataset from “ICDAR2019 Competition on Scanned Receipt OCR and Information Extraction”.
>>> from doctr.datasets import SROIE
>>> train_set = SROIE(train=True, download=True)
>>> sample = train_set[0]
>>> img, target = sample.image, sample.target
- Parameters:
train (bool) – whether the subset should be the training one
use_polygons (bool) – whether polygons should be considered as rotated bounding box (instead of straight ones)
recognition_task (bool) – whether the dataset should be used for recognition task
detection_task (bool) – whether the dataset should be used for detection task
**kwargs (Any) – keyword arguments from VisionDataset.
- class CORD(
- train=True,
- use_polygons=False,
- recognition_task=False,
- detection_task=False,
- **kwargs,
CORD dataset from “CORD: A Consolidated Receipt Dataset forPost-OCR Parsing”.
>>> from doctr.datasets import CORD
>>> train_set = CORD(train=True, download=True)
>>> sample = train_set[0]
>>> img, target = sample.image, sample.target
- Parameters:
train (bool) – whether the subset should be the training one
use_polygons (bool) – whether polygons should be considered as rotated bounding box (instead of straight ones)
recognition_task (bool) – whether the dataset should be used for recognition task
detection_task (bool) – whether the dataset should be used for detection task
**kwargs (Any) – keyword arguments from VisionDataset.
- class IIIT5K(
- train=True,
- use_polygons=False,
- recognition_task=False,
- detection_task=False,
- **kwargs,
IIIT-5K character-level localization dataset from “BMVC 2012 Scene Text Recognition using Higher Order Language Priors”.
>>> # NOTE: this dataset is for character-level localization
>>> from doctr.datasets import IIIT5K
>>> train_set = IIIT5K(train=True, download=True)
>>> sample = train_set[0]
>>> img, target = sample.image, sample.target
- Parameters:
train (bool) – whether the subset should be the training one
use_polygons (bool) – whether polygons should be considered as rotated bounding box (instead of straight ones)
recognition_task (bool) – whether the dataset should be used for recognition task
detection_task (bool) – whether the dataset should be used for detection task
**kwargs (Any) – keyword arguments from VisionDataset.
- class SVT(
- train=True,
- use_polygons=False,
- recognition_task=False,
- detection_task=False,
- **kwargs,
SVT dataset from “The Street View Text Dataset - UCSD Computer Vision”.
>>> from doctr.datasets import SVT
>>> train_set = SVT(train=True, download=True)
>>> sample = train_set[0]
>>> img, target = sample.image, sample.target
- Parameters:
train (bool) – whether the subset should be the training one
use_polygons (bool) – whether polygons should be considered as rotated bounding box (instead of straight ones)
recognition_task (bool) – whether the dataset should be used for recognition task
detection_task (bool) – whether the dataset should be used for detection task
**kwargs (Any) – keyword arguments from VisionDataset.
- class SVHN(
- train=True,
- use_polygons=False,
- recognition_task=False,
- detection_task=False,
- **kwargs,
SVHN dataset from “The Street View House Numbers (SVHN) Dataset”.
>>> from doctr.datasets import SVHN
>>> train_set = SVHN(train=True, download=True)
>>> sample = train_set[0]
>>> img, target = sample.image, sample.target
- Parameters:
train (bool) – whether the subset should be the training one
use_polygons (bool) – whether polygons should be considered as rotated bounding box (instead of straight ones)
recognition_task (bool) – whether the dataset should be used for recognition task
detection_task (bool) – whether the dataset should be used for detection task
**kwargs (Any) – keyword arguments from VisionDataset.
- class SynthText(
- train=True,
- use_polygons=False,
- recognition_task=False,
- detection_task=False,
- **kwargs,
SynthText dataset from “Synthetic Data for Text Localisation in Natural Images” | “repository” | “website”.
>>> from doctr.datasets import SynthText
>>> train_set = SynthText(train=True, download=True)
>>> sample = train_set[0]
>>> img, target = sample.image, sample.target
- Parameters:
train (bool) – whether the subset should be the training one
use_polygons (bool) – whether polygons should be considered as rotated bounding box (instead of straight ones)
recognition_task (bool) – whether the dataset should be used for recognition task
detection_task (bool) – whether the dataset should be used for detection task
**kwargs (Any) – keyword arguments from VisionDataset.
- class IC03(
- train=True,
- use_polygons=False,
- recognition_task=False,
- detection_task=False,
- **kwargs,
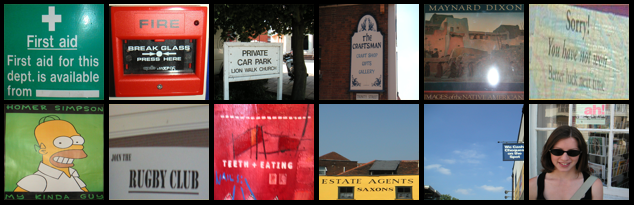
IC03 dataset from “ICDAR 2003 Robust Reading Competitions: Entries, Results and Future Directions”.
>>> from doctr.datasets import IC03
>>> train_set = IC03(train=True, download=True)
>>> sample = train_set[0]
>>> img, target = sample.image, sample.target
- Parameters:
train (bool) – whether the subset should be the training one
use_polygons (bool) – whether polygons should be considered as rotated bounding box (instead of straight ones)
recognition_task (bool) – whether the dataset should be used for recognition task
detection_task (bool) – whether the dataset should be used for detection task
**kwargs (Any) – keyword arguments from VisionDataset.
- class IC13(
- img_folder,
- label_folder,
- use_polygons=False,
- recognition_task=False,
- detection_task=False,
- **kwargs,
IC13 dataset from “ICDAR 2013 Robust Reading Competition”.
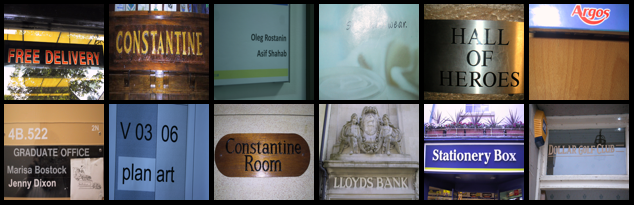
>>> # NOTE: You need to download both image and label parts from Focused Scene Text challenge Task2.1 2013-2015.
>>> from doctr.datasets import IC13
>>> train_set = IC13(img_folder="/path/to/Challenge2_Training_Task12_Images",
>>>                  label_folder="/path/to/Challenge2_Training_Task1_GT")
>>> sample = train_set[0]
>>> img, target = sample.image, sample.target
>>> test_set = IC13(img_folder="/path/to/Challenge2_Test_Task12_Images",
>>>                 label_folder="/path/to/Challenge2_Test_Task1_GT")
>>> sample = test_set[0]
>>> img, target = sample.image, sample.target
- Parameters:
img_folder (str) – folder with all the images of the dataset
label_folder (str) – folder with all annotation files for the images
use_polygons (bool) – whether polygons should be considered as rotated bounding box (instead of straight ones)
recognition_task (bool) – whether the dataset should be used for recognition task
detection_task (bool) – whether the dataset should be used for detection task
**kwargs (Any) – keyword arguments from AbstractDataset.
- class IMGUR5K(
- img_folder,
- label_path,
- train=True,
- use_polygons=False,
- recognition_task=False,
- detection_task=False,
- **kwargs,
IMGUR5K dataset from “TextStyleBrush: Transfer of Text Aesthetics from a Single Example” | repository.
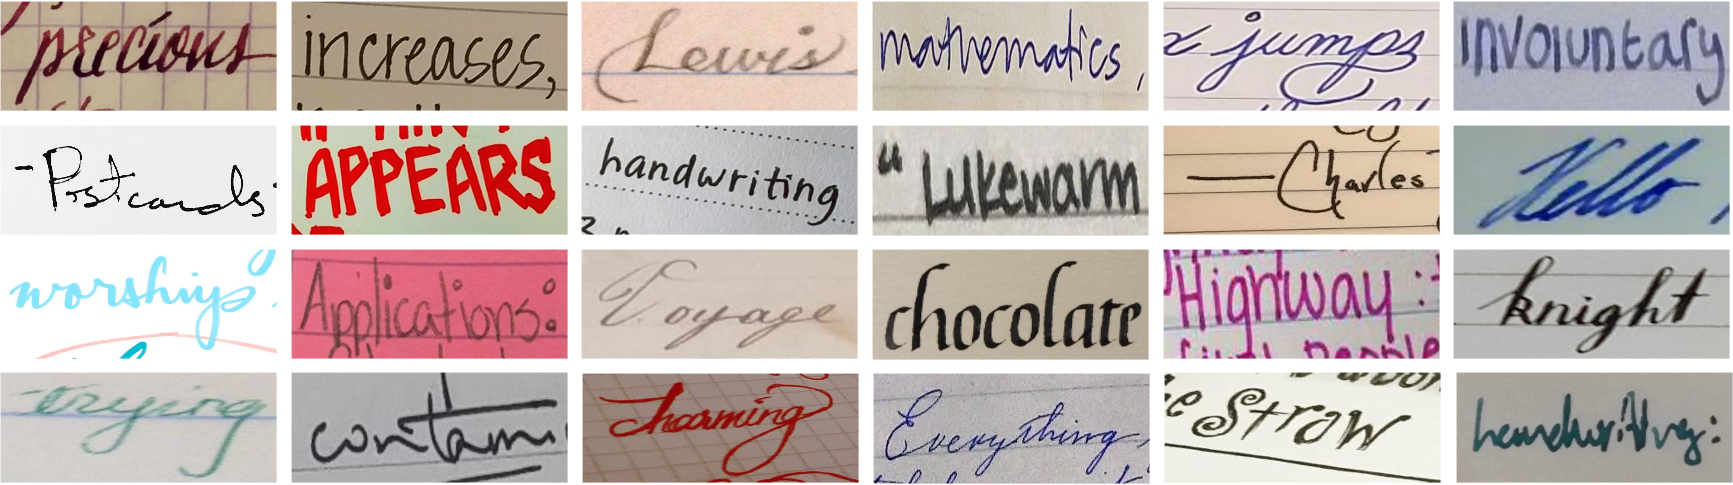
>>> # NOTE: You need to download/generate the dataset from the repository.
>>> from doctr.datasets import IMGUR5K
>>> train_set = IMGUR5K(train=True, img_folder="/path/to/IMGUR5K-Handwriting-Dataset/images",
>>>                     label_path="/path/to/IMGUR5K-Handwriting-Dataset/dataset_info/imgur5k_annotations.json")
>>> sample = train_set[0]
>>> img, target = sample.image, sample.target
>>> test_set = IMGUR5K(train=False, img_folder="/path/to/IMGUR5K-Handwriting-Dataset/images",
>>>                    label_path="/path/to/IMGUR5K-Handwriting-Dataset/dataset_info/imgur5k_annotations.json")
>>> sample = test_set[0]
>>> img, target = sample.image, sample.target
- Parameters:
img_folder (str) – folder with all the images of the dataset
label_path (str) – path to the annotations file of the dataset
train (bool) – whether the subset should be the training one
use_polygons (bool) – whether polygons should be considered as rotated bounding box (instead of straight ones)
recognition_task (bool) – whether the dataset should be used for recognition task
detection_task (bool) – whether the dataset should be used for detection task
**kwargs (Any) – keyword arguments from AbstractDataset.
- class MJSynth(img_folder, label_path, train=True, **kwargs)[source]#
MJSynth dataset from “Synthetic Data and Artificial Neural Networks for Natural Scene Text Recognition”.
>>> # NOTE: This is a pure recognition dataset without bounding box labels.
>>> # NOTE: You need to download the dataset.
>>> from doctr.datasets import MJSynth
>>> train_set = MJSynth(img_folder="/path/to/mjsynth/mnt/ramdisk/max/90kDICT32px",
>>>                     label_path="/path/to/mjsynth/mnt/ramdisk/max/90kDICT32px/imlist.txt",
>>>                     train=True)
>>> sample = train_set[0]
>>> img, target = sample.image, sample.target
>>> test_set = MJSynth(img_folder="/path/to/mjsynth/mnt/ramdisk/max/90kDICT32px",
>>>                    label_path="/path/to/mjsynth/mnt/ramdisk/max/90kDICT32px/imlist.txt")
>>>                    train=False)
>>> sample = test_set[0]
>>> img, target = sample.image, sample.target
- class IIITHWS(img_folder, label_path, train=True, **kwargs)[source]#
IIITHWS dataset from “Generating Synthetic Data for Text Recognition” | “repository” | “website”.
>>> # NOTE: This is a pure recognition dataset without bounding box labels.
>>> # NOTE: You need to download the dataset.
>>> from doctr.datasets import IIITHWS
>>> train_set = IIITHWS(img_folder="/path/to/iiit-hws/Images_90K_Normalized",
>>>                     label_path="/path/to/IIIT-HWS-90K.txt",
>>>                     train=True)
>>> sample = train_set[0]
>>> img, target = sample.image, sample.target
>>> test_set = IIITHWS(img_folder="/path/to/iiit-hws/Images_90K_Normalized",
>>>                    label_path="/path/to/IIIT-HWS-90K.txt")
>>>                    train=False)
>>> sample = test_set[0]
>>> img, target = sample.image, sample.target
- class DocArtefacts(train=True, use_polygons=False, **kwargs)[source]#
Object detection dataset for non-textual elements in documents. The dataset includes a variety of synthetic document pages with non-textual elements.
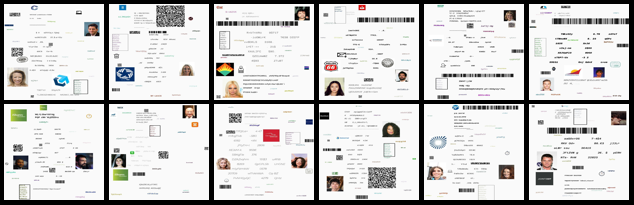
>>> from doctr.datasets import DocArtefacts
>>> train_set = DocArtefacts(train=True, download=True)
>>> sample = train_set[0]
>>> img, target = sample.image, sample.target
- class WILDRECEIPT(
- img_folder,
- label_path,
- train=True,
- use_polygons=False,
- recognition_task=False,
- detection_task=False,
- **kwargs,
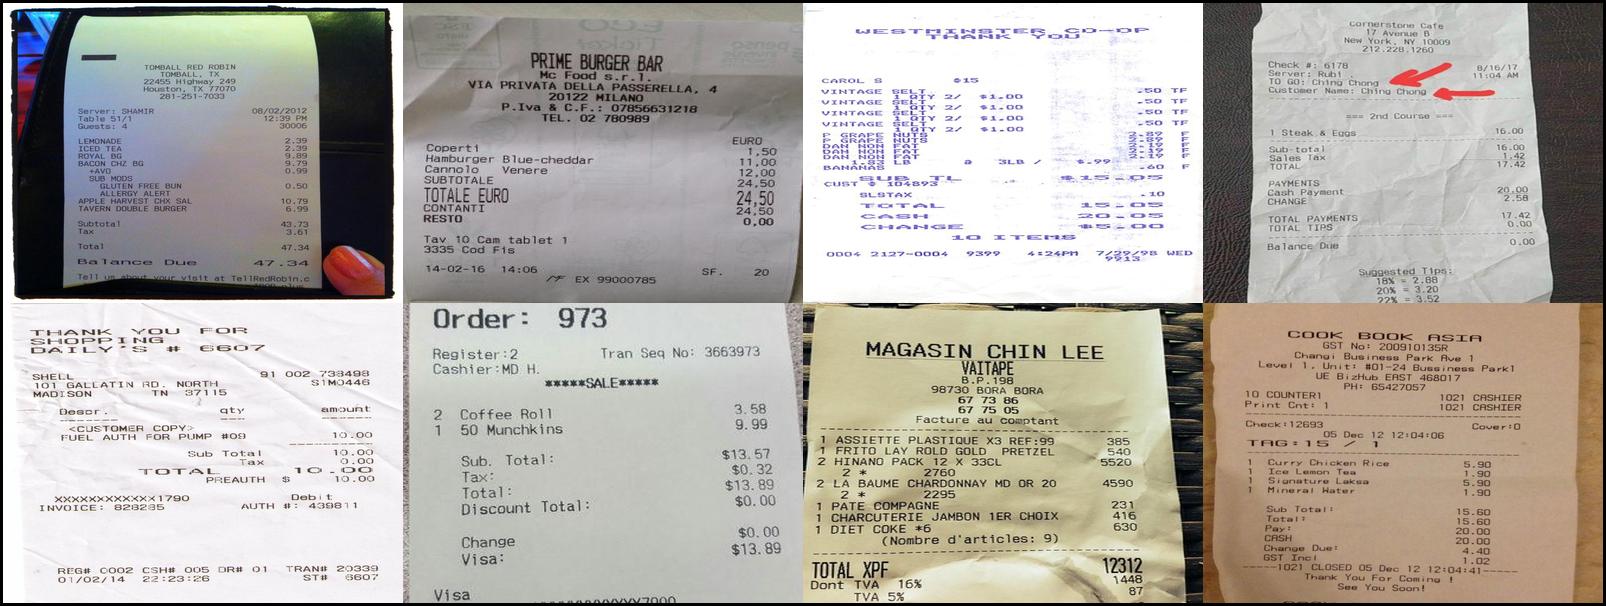
WildReceipt dataset from “Spatial Dual-Modality Graph Reasoning for Key Information Extraction” | “repository”.
>>> # NOTE: You need to download the dataset first.
>>> from doctr.datasets import WILDRECEIPT
>>> train_set = WILDRECEIPT(train=True, img_folder="/path/to/wildreceipt/",
>>>                     label_path="/path/to/wildreceipt/train.txt")
>>> sample = train_set[0]
>>> img, target = sample.image, sample.target
>>> test_set = WILDRECEIPT(train=False, img_folder="/path/to/wildreceipt/",
>>>                    label_path="/path/to/wildreceipt/test.txt")
>>> sample = test_set[0]
>>> img, target = sample.image, sample.target
- Parameters:
img_folder (str) – folder with all the images of the dataset
label_path (str) – path to the annotations file of the dataset
train (bool) – whether the subset should be the training one
use_polygons (bool) – whether polygons should be considered as rotated bounding box (instead of straight ones)
recognition_task (bool) – whether the dataset should be used for recognition task
detection_task (bool) – whether the dataset should be used for detection task
**kwargs (Any) – keyword arguments from AbstractDataset.
- class COCOTEXT(
- img_folder,
- label_path,
- train=True,
- use_polygons=False,
- recognition_task=False,
- detection_task=False,
- **kwargs,
COCO-Text dataset from “COCO-Text: Dataset and Benchmark for Text Detection and Recognition in Natural Images” | “homepage”.
>>> # NOTE: You need to download the dataset first.
>>> from doctr.datasets import COCOTEXT
>>> train_set = COCOTEXT(train=True, img_folder="/path/to/coco_text/train2014/",
>>>                     label_path="/path/to/coco_text/cocotext.v2.json")
>>> sample = train_set[0]
>>> img, target = sample.image, sample.target
>>> test_set = COCOTEXT(train=False, img_folder="/path/to/coco_text/train2014/",
>>> label_path = "/path/to/coco_text/cocotext.v2.json")
>>> sample = test_set[0]
>>> img, target = sample.image, sample.target
- Parameters:
img_folder (str) – folder with all the images of the dataset
label_path (str) – path to the annotations file of the dataset
train (bool) – whether the subset should be the training one
use_polygons (bool) – whether polygons should be considered as rotated bounding box (instead of straight ones)
recognition_task (bool) – whether the dataset should be used for recognition task
detection_task (bool) – whether the dataset should be used for detection task
**kwargs (Any) – keyword arguments from AbstractDataset.
Synthetic dataset generator#
- class CharacterGenerator(*args, **kwargs)[source]#
Implements a character image generation dataset
>>> from doctr.datasets import CharacterGenerator
>>> ds = CharacterGenerator(vocab='abdef', num_samples=100)
>>> sample = ds[0]
>>> img, target = sample.image, sample.target
- Parameters:
vocab – vocabulary to take the character from
num_samples – number of samples that will be generated iterating over the dataset
cache_samples – whether generated images should be cached firsthand
font_family – font to use to generate the text images
img_transforms – composable transformations that will be applied to each image
sample_transforms – composable transformations that will be applied to both the image and the target
- class WordGenerator(
- vocab,
- min_chars,
- max_chars,
- num_samples,
- cache_samples=False,
- font_family=None,
- img_transforms=None,
- sample_transforms=None,
Implements a character image generation dataset
>>> from doctr.datasets import WordGenerator
>>> ds = WordGenerator(vocab='abdef', min_chars=1, max_chars=32, num_samples=100)
>>> sample = ds[0]
>>> img, target = sample.image, sample.target
- Parameters:
vocab (str) – vocabulary to take the character from
min_chars (int) – minimum number of characters in a word
max_chars (int) – maximum number of characters in a word
num_samples (int) – number of samples that will be generated iterating over the dataset
cache_samples (bool) – whether generated images should be cached firsthand
font_family (str | list[str] | None) – font to use to generate the text images
img_transforms (Callable[[Any], Any] | None) – composable transformations that will be applied to each image
sample_transforms (Callable[[Sample], Sample] | None) – composable transformations that will be applied to both the image and the target
Custom dataset loader#
- class DetectionDataset(img_folder, label_path, use_polygons=False, **kwargs)[source]#
Implements a text detection dataset
>>> from doctr.datasets import DetectionDataset
>>> train_set = DetectionDataset(img_folder="/path/to/images",
>>>                              label_path="/path/to/labels.json")
>>> sample = train_set[0]
>>> img, target = sample.image, sample.target
- class LayoutDataset(img_folder, label_path, use_polygons=False, **kwargs)[source]#
Implements a document layout detection dataset.
>>> from doctr.datasets import LayoutDataset
>>> train_set = LayoutDataset(
>>>     img_folder="/path/to/images",
>>>     label_path="/path/to/labels.json",
>>> )
>>> sample = train_set[0]
>>> img, target = sample.image, sample.target
- class RecognitionDataset(img_folder, labels_path, **kwargs)[source]#
Dataset implementation for text recognition tasks
>>> from doctr.datasets import RecognitionDataset
>>> train_set = RecognitionDataset(img_folder="/path/to/images",
>>>                                labels_path="/path/to/labels.json")
>>> sample = train_set[0]
>>> img, target = sample.image, sample.target
- class TableStructureDataset(img_folder, label_path, use_polygons=False, **kwargs)[source]#
Table structure recognition dataset for table structure recognition.
The labels file maps each image name to its cells and their logical coordinates:
{
    "table_0.jpg": {
        "cells": [[[x0, y0], [x1, y1], [x2, y2], [x3, y3]], ...],   # quads (TL, TR, BR, BL), abs px
        "logic": [[start_col, end_col, start_row, end_row], ...]      # 0-indexed, per cell
    },
    ...
}
Each sample yields the image and a target containing relative cells and their logical coordinates. Cells have shape (N, 4) by default, or (N, 4, 2) when use_polygons=True. Logical coordinates have shape (N, 4).
>>> from doctr.datasets import TableStructureDataset
>>> from doctr.transforms import Resize
>>> train_set = TableStructureDataset(
>>>     img_folder="/path/to/images",
>>>     label_path="/path/to/labels.json",
>>> )
>>> img, target = train_set[0]
- Parameters:
- class OCRDataset(img_folder, label_file, use_polygons=False, **kwargs)[source]#
Implements an OCR dataset
>>> from doctr.datasets import OCRDataset
>>> train_set = OCRDataset(img_folder="/path/to/images",
>>>                        label_file="/path/to/labels.json")
>>> sample = train_set[0]
>>> img, target = sample.image, sample.target
Dataset utils#
- translate(input_string, vocab_name, unknown_char='■')[source]#
Translate a string input in a given vocabulary
- encode_string(input_string, vocab)[source]#
Given a predefined mapping, encode the string to a sequence of numbers
- decode_sequence(input_seq, mapping)[source]#
Given a predefined mapping, decode the sequence of numbers to a string
- encode_sequences(
- sequences,
- vocab,
- target_size=None,
- eos=-1,
- sos=None,
- pad=None,
- dynamic_seq_length=False,
Encode character sequences using a given vocab as mapping
- Parameters:
sequences (list[str]) – the list of character sequences of size N
vocab (str) – the ordered vocab to use for encoding
target_size (int | None) – maximum length of the encoded data
eos (int) – encoding of End Of String
sos (int | None) – optional encoding of Start Of String
pad (int | None) – optional encoding for padding. In case of padding, all sequences are followed by 1 EOS then PAD
dynamic_seq_length (bool) – if target_size is specified, uses it as upper bound and enables dynamic sequence size
- Returns:
the padded encoded data as a tensor
- Return type:
Supported Vocabs#
Since textual content has to be encoded properly for models to interpret them efficiently, docTR supports multiple sets of vocabs.
Name |
size |
characters |
|---|---|---|
latex |
82 |
abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ0123456789\{}^_=+-<>()[]/.,| |
latin |
94 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~ |
english |
100 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿ |
albanian |
104 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿çëÇË |
afrikaans |
114 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿èëïîôûêÈËÏÎÔÛÊ |
azerbaijani |
111 |
0123456789abcdefghijklmnopqrstuvxyzABCDEFGHIJKLMNOPQRSTUVXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿çəğöşüÇƏĞÖŞÜ₼ |
basque |
104 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿ñçÑÇ |
bosnian |
102 |
0123456789abcdefghijklmnoprstuvzABCDEFGHIJKLMNOPRSTUVZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿čćđšžČĆĐŠŽ |
catalan |
120 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿àèéíïòóúüçÀÈÉÍÏÒÓÚÜÇ |
croatian |
110 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿ČčĆćĐ𩹮ž |
czech |
130 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿áčďéěíňóřšťúůýžÁČĎÉĚÍŇÓŘŠŤÚŮÝŽ |
danish |
106 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿æøåÆØÅ |
dutch |
114 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿áéíóúüñÁÉÍÓÚÜÑ |
estonian |
112 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿šžõäöüŠŽÕÄÖÜ |
esperanto |
105 |
0123456789abcdefghijklmnoprstuvzABCDEFGHIJKLMNOPRSTUVZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿ĉĝĥĵŝŭĈĜĤĴŜŬ₷ |
french |
126 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿àâéèêëîïôùûüçÀÂÉÈÊËÎÏÔÙÛÜÇ |
finnish |
104 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿äöÄÖ |
frisian |
108 |
0123456789abcdefghijklmnoprstuvwyzABCDEFGHIJKLMNOPRSTUVWYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿âêôûúÂÊÔÛÚƒƑ |
galician |
98 |
0123456789abcdefghilmnopqrstuvxyzABCDEFGHILMNOPQRSTUVXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿ñÑçÇ |
german |
108 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿äöüßÄÖÜẞ |
hausa |
101 |
0123456789abcdefghijklmnorstuwyzABCDEFGHIJKLMNORSTUWYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿ɓɗƙƴƁƊƘƳ₦ |
hungarian |
114 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿áéíóöúüÁÉÍÓÖÚÜ |
icelandic |
114 |
0123456789abdefghijklmnoprstuvxyzABDEFGHIJKLMNOPRSTUVXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿ðáéíóúýþæöÐÁÉÍÓÚÝÞÆÖ |
indonesian |
100 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿ |
irish |
110 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿áéíóúÁÉÍÓÚ |
italian |
120 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿àèéìíîòóùúÀÈÉÌÍÎÒÓÙÚ |
latvian |
116 |
0123456789abcdefghijklmnoprstuvyzABCDEFGHIJKLMNOPRSTUVYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿āčēģīķļņšūžĀČĒĢĪĶĻŅŠŪŽ |
lithuanian |
112 |
0123456789abcdefghijklmnoprstuvyzABCDEFGHIJKLMNOPRSTUVYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿ąčęėįšųūžĄČĘĖĮŠŲŪŽ |
luxembourgish |
110 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿äöüéëÄÖÜÉË |
malagasy |
94 |
0123456789abdefghijklmnoprstvyzABDEFGHIJKLMNOPRSTVYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿ôñÔÑ |
malay |
100 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿ |
maltese |
104 |
0123456789abdefghijklmnopqrstuvwxzABDEFGHIJKLMNOPQRSTUVWXZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿ċġħżĊĠĦŻ |
maori |
84 |
0123456789aeghikmnprtuwAEGHIKMNPRTUW!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿āēīōūĀĒĪŌŪ |
montenegrin |
103 |
0123456789abcdefghijklmnoprstuvzABCDEFGHIJKLMNOPRSTUVZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿čćšžźČĆŠŚŽŹ |
norwegian |
106 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿æøåÆØÅ |
polish |
118 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿ąćęłńóśźżĄĆĘŁŃÓŚŹŻ |
portuguese |
128 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿áàâãéêíïóôõúüçÁÀÂÃÉÊÍÏÓÔÕÚÜÇ |
quechua |
90 |
0123456789acehiklmnopqrstuwyACEHIKLMNOPQRSTUWY!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿ñÑĉĈçÇ |
romanian |
110 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿ăâîșțĂÂÎȘȚ |
scottish_gaelic |
94 |
0123456789abcdefghilmnoprstuABCDEFGHILMNOPRSTU!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿àèìòùÀÈÌÒÙ |
serbian_latin |
110 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿čćđžšČĆĐŽŠ |
slovak |
134 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿ôäčďľňšťžáéíĺóŕúýÔÄČĎĽŇŠŤŽÁÉÍĹÓŔÚÝ |
slovene |
102 |
0123456789abcdefghijklmnoprstuvzABCDEFGHIJKLMNOPRSTUVZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿čćđšžČĆĐŠŽ |
somali |
94 |
0123456789abcdefghijklmnoqrstuwxyABCDEFGHIJKLMNOQRSTUWXY!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿ |
spanish |
116 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿áéíóúüñÁÉÍÓÚÜÑ¡¿ |
swahili |
96 |
0123456789abcdefghijklmnoprstuvwyzABCDEFGHIJKLMNOPRSTUVWYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿ |
swedish |
106 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿åäöÅÄÖ |
tagalog |
95 |
0123456789abdefghijklmnoprstuvyzABDEFGHIJKLMNOPRSTUVYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿ñÑ₱ |
turkish |
113 |
0123456789abcdefghijklmnoprstuvyzABCDEFGHIJKLMNOPRSTUVYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿çğıöşüâîûÇĞİÖŞÜÂÎÛ₺ |
uzbek_latin |
110 |
0123456789abcdefghijklmnopqrstuvxyzABCDEFGHIJKLMNOPQRSTUVXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿çğɉñöşÇĞɈÑÖŞ |
vietnamese |
235 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿áàảạãăắằẳẵặâấầẩẫậđéèẻẽẹêếềểễệóòỏõọôốồổộỗơớờởợỡúùủũụưứừửữựíìỉĩịýỳỷỹỵÁÀẢẠÃĂẮẰẲẴẶÂẤẦẨẪẬĐÉÈẺẼẸÊẾỀỂỄỆÓÒỎÕỌÔỐỒỔỘỖƠỚỜỞỢỠÚÙỦŨỤƯỨỪỬỮỰÍÌỈĨỊÝỲỶỸỴ₫ |
welsh |
102 |
0123456789abcdefghijlmnoprstuwyABCDEFGHIJLMNOPRSTUWY!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿âêîôŵŷÂÊÎÔŴŶ |
yoruba |
97 |
0123456789abdefghijklmnoprstuwyABDEFGHIJKLMNOPRSTUWY!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿ẹọṣẸỌṢ₦ |
zulu |
100 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿ |
russian |
114 |
абвгдежзийклмнопрстуфхцчшщьюяАБВГДЕЖЗИЙКЛМНОПРСТУФХЦЧШЩЬЮЯёыэЁЫЭъЪ0123456789!”#$%&’()*+,-./:;<=>?@[]^_`{|}~£€¥¢฿₽ |
belarusian |
116 |
абвгдежзийклмнопрстуфхцчшщьюяАБВГДЕЖЗИЙКЛМНОПРСТУФХЦЧШЩЬЮЯёыэЁЫЭ0123456789!”#$%&’()*+,-./:;<=>?@[]^_`{|}~£€¥¢฿ўiЎI₽ |
ukrainian |
114 |
абвгдежзийклмнопрстуфхцчшщьюяАБВГДЕЖЗИЙКЛМНОПРСТУФХЦЧШЩЬЮЯ0123456789!”#$%&’()*+,-./:;<=>?@[]^_`{|}~£€¥¢฿ґіїєҐІЇЄ₴ |
tatar |
124 |
абвгдежзийклмнопрстуфхцчшщьюяАБВГДЕЖЗИЙКЛМНОПРСТУФХЦЧШЩЬЮЯёыэЁЫЭъЪ0123456789!”#$%&’()*+,-./:;<=>?@[]^_`{|}~£€¥¢฿₽ӘәҖҗҢңӨөҮү |
tajik |
125 |
абвгдежзийклмнопрстуфхцчшщьюяАБВГДЕЖЗИЙКЛМНОПРСТУФХЦЧШЩЬЮЯёыэЁЫЭъЪ0123456789!”#$%&’()*+,-./:;<=>?@[]^_`{|}~£€¥¢฿ҒғҚқҲҳҶҷӢӣӮӯ |
kazakh |
132 |
абвгдежзийклмнопрстуфхцчшщьюяАБВГДЕЖЗИЙКЛМНОПРСТУФХЦЧШЩЬЮЯёыэЁЫЭъЪ0123456789!”#$%&’()*+,-./:;<=>?@[]^_`{|}~£€¥¢฿ӘәҒғҚқҢңӨөҰұҮүҺһІі₸ |
kyrgyz |
119 |
абвгдежзийклмнопрстуфхцчшщьюяАБВГДЕЖЗИЙКЛМНОПРСТУФХЦЧШЩЬЮЯёыэЁЫЭъЪ0123456789!”#$%&’()*+,-./:;<=>?@[]^_`{|}~£€¥¢฿ҢңӨөҮү |
bulgarian |
107 |
абвгдежзийклмнопрстуфхцчшщьюяАБВГДЕЖЗИЙКЛМНОПРСТУФХЦЧШЩЬЮЯъЪ0123456789!”#$%&’()*+,-./:;<=>?@[]^_`{|}~£€¥¢฿ |
macedonian |
119 |
абвгдежзийклмнопрстуфхцчшщьюяАБВГДЕЖЗИЙКЛМНОПРСТУФХЦЧШЩЬЮЯ0123456789!”#$%&’()*+,-./:;<=>?@[]^_`{|}~£€¥¢฿ЃѓЅѕЈјЉљЊњЌќЏџ |
mongolian |
128 |
абвгдежзийклмнопрстуфхцчшщьюяАБВГДЕЖЗИЙКЛМНОПРСТУФХЦЧШЩЬЮЯёыэЁЫЭъЪ0123456789!”#$%&’()*+,-./:;<=>?@[]^_`{|}~£€¥¢฿ӨөҮү᠐᠑᠒᠓᠔᠕᠖᠗᠘᠙₮ |
yakut |
124 |
абвгдежзийклмнопрстуфхцчшщьюяАБВГДЕЖЗИЙКЛМНОПРСТУФХЦЧШЩЬЮЯёыэЁЫЭъЪ0123456789!”#$%&’()*+,-./:;<=>?@[]^_`{|}~£€¥¢฿ҔҕҤҥӨөҺһҮү₽ |
serbian_cyrillic |
107 |
абвгдежзиклмнопрстуфхцчшАБВГДЕЖЗИКЛМНОПРСТУФХЦЧШJjЂђЉљЊњЋћЏџ0123456789!”#$%&’()*+,-./:;<=>?@[]^_`{|}~£€¥¢฿ |
uzbek_cyrillic |
121 |
абвгдежзийклмнопрстуфхцчшщьюяАБВГДЕЖЗИЙКЛМНОПРСТУФХЦЧШЩЬЮЯёыэЁЫЭъЪ0123456789!”#$%&’()*+,-./:;<=>?@[]^_`{|}~£€¥¢฿ЎўҚқҒғҲҳ |
greek |
106 |
!”#$%&’()*+,-./:;<=>?@[]^_`{|}~αβγδεζηθικλμνξοπρστςυφχψωΑΒΓΔΕΖΗΘΙΚΛΜΝΞΟΠΡΣΤΥΦΧΨΩ£€¥¢฿άέήίϊΐόύϋΰώΆΈΉΊΪΌΎΫΏ |
greek_extended |
301 |
!”#$%&’()*+,-./:;<=>?@[]^_`{|}~αβγδεζηθικλμνξοπρστςυφχψωΑΒΓΔΕΖΗΘΙΚΛΜΝΞΟΠΡΣΤΥΦΧΨΩ£€¥¢฿άέήίϊΐόύϋΰώΆΈΉΊΪΌΎΫΏͶͷϜϝἀἁἂἃἄἅἆἇἈἉἊἋἌἍἎἏἐἑἒἓἔἕἘἙἚἛἜἝἠἡἢἣἤἥἦἧἨἩἪἫἬἭἮἯἰἱἲἳἴἵἶἷἸἹἺἻἼἽἾἿὀὁὂὃὄὅὈὉὊὋὌὍὐὑὒὓὔὕὖὗὙὛὝὟὠὡὢὣὤὥὦὧὨὩὪὫὬὭὮὯὰὲὴὶὸὺὼᾀᾁᾂᾃᾄᾅᾆᾇᾈᾉᾊᾋᾌᾍᾎᾏᾐᾑᾒᾓᾔᾕᾖᾗᾘᾙᾚᾛᾜᾝᾞᾟᾠᾡᾢᾣᾤᾥᾦᾧᾨᾩᾪᾫᾬᾭᾮᾯᾲᾳᾴᾶᾷᾺᾼῂῃῄῆῇῈῊῌῒΐῖῗῚῢΰῤῥῦῧῪῬῲῳῴῶῷῸῺῼ |
hebrew |
176 |
0123456789!”#$%&’()*+,-./:;<=>?@[]^_`{|}~אבגדהוזחטיךכלםמןנסעףפץצקרשתְֱֲֳִֵֶַָׇֹֺֻֽ־ֿ׀ׁׂ׃ׅׄ׆׳״֑֖֛֢֣֤֥֦֧֪֚֭֮֒֓֔֕֗֘֙֜֝֞֟֠֡֨֩֫֬֯ׯװױײיִﬞײַﬠﬡﬢﬣﬤﬥﬦﬧﬨ﬩שׁשׂשּׁשּׂאַאָאּבּגּדּהּוּזּטּיּךּכּלּמּנּסּףּפּצּקּרּשּתּוֹבֿכֿפֿﭏ₪ |
arabic |
116 |
0123456789٠١٢٣٤٥٦٧٨٩ءآأؤإئابةتثجحخدذرزسشصضطظعغـفقكلمنهوىيٱپچژڢڤگکیًٌٍَُِّْٕٓٔٚ؟؛«»—،!”#$%&’()*+,-./:;<=>?@[]^_`{|}~ |
persian |
116 |
0123456789٠١٢٣٤٥٦٧٨٩ءآأؤإئابةتثجحخدذرزسشصضطظعغـفقكلمنهوىيٱپچژڢڤگکیًٌٍَُِّْٕٓٔٚ؟؛«»—،!”#$%&’()*+,-./:;<=>?@[]^_`{|}~ |
urdu |
124 |
0123456789٠١٢٣٤٥٦٧٨٩ءآأؤإئابةتثجحخدذرزسشصضطظعغـفقكلمنهوىيٱپچژڢڤگکیًٌٍَُِّْٕٓٔٚ؟؛«»—،!”#$%&’()*+,-./:;<=>?@[]^_`{|}~ٹڈڑںھےہۃ |
pashto |
126 |
0123456789٠١٢٣٤٥٦٧٨٩ءآأؤإئابةتثجحخدذرزسشصضطظعغـفقكلمنهوىيٱپچژڢڤگکیًٌٍَُِّْٕٓٔٚ؟؛«»—،!”#$%&’()*+,-./:;<=>?@[]^_`{|}~ټډړږښځڅڼېۍ |
kurdish |
121 |
0123456789٠١٢٣٤٥٦٧٨٩ءآأؤإئابةتثجحخدذرزسشصضطظعغـفقكلمنهوىيٱپچژڢڤگکیًٌٍَُِّْٕٓٔٚ؟؛«»—،!”#$%&’()*+,-./:;<=>?@[]^_`{|}~ڵڕۆێە |
uyghur |
123 |
0123456789٠١٢٣٤٥٦٧٨٩ءآأؤإئابةتثجحخدذرزسشصضطظعغـفقكلمنهوىيٱپچژڢڤگکیًٌٍَُِّْٕٓٔٚ؟؛«»—،!”#$%&’()*+,-./:;<=>?@[]^_`{|}~ەېۆۇۈڭھ |
sindhi |
133 |
0123456789٠١٢٣٤٥٦٧٨٩ءآأؤإئابةتثجحخدذرزسشصضطظعغـفقكلمنهوىيٱپچژڢڤگکیًٌٍَُِّْٕٓٔٚ؟؛«»—،!”#$%&’()*+,-./:;<=>?@[]^_`{|}~ڀٿٺٽڦڄڃڇڏڌڊڍڙڳڱڻھ |
devanagari |
151 |
कखगघङचछजझञटठडढणतथदधनपफबभमयरलवशषसहऴऩळक़ख़ग़ज़ड़ढ़फ़य़ऱॺॻॼॽॾअआइईउऊऋऌऍऎएऐऑऒओऔॠॡॲऄॵॶॳॴॷॸॹ०१२३४५६७८९़ंँः॒॑ािीुूृॄॅॆेैॉॊोौॢॣॏॎ्।॥॰ऽꣲ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~₹ |
hindi |
151 |
कखगघङचछजझञटठडढणतथदधनपफबभमयरलवशषसहऴऩळक़ख़ग़ज़ड़ढ़फ़य़ऱॺॻॼॽॾअआइईउऊऋऌऍऎएऐऑऒओऔॠॡॲऄॵॶॳॴॷॸॹ०१२३४५६७८९़ंँः॒॑ािीुूृॄॅॆेैॉॊोौॢॣॏॎ्।॥॰ऽꣲ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~₹ |
sanskrit |
151 |
कखगघङचछजझञटठडढणतथदधनपफबभमयरलवशषसहऴऩळक़ख़ग़ज़ड़ढ़फ़य़ऱॺॻॼॽॾअआइईउऊऋऌऍऎएऐऑऒओऔॠॡॲऄॵॶॳॴॷॸॹ०१२३४५६७८९़ंँः॒॑ािीुूृॄॅॆेैॉॊोौॢॣॏॎ्।॥॰ऽꣲ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~₹ |
marathi |
151 |
कखगघङचछजझञटठडढणतथदधनपफबभमयरलवशषसहऴऩळक़ख़ग़ज़ड़ढ़फ़य़ऱॺॻॼॽॾअआइईउऊऋऌऍऎएऐऑऒओऔॠॡॲऄॵॶॳॴॷॸॹ०१२३४५६७८९़ंँः॒॑ािीुूृॄॅॆेैॉॊोौॢॣॏॎ्।॥॰ऽꣲ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~₹ |
nepali |
151 |
कखगघङचछजझञटठडढणतथदधनपफबभमयरलवशषसहऴऩळक़ख़ग़ज़ड़ढ़फ़य़ऱॺॻॼॽॾअआइईउऊऋऌऍऎएऐऑऒओऔॠॡॲऄॵॶॳॴॷॸॹ०१२३४५६७८९़ंँः॒॑ािीुूृॄॅॆेैॉॊोौॢॣॏॎ्।॥॰ऽꣲ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~₹ |
gujarati |
121 |
કખગઘઙચછજઝઞટઠડઢણતથદધનપફબભમયરલળવશષસહઅઆઇઈઉઊઋઌઍએઐઑઓઔ૦૧૨૩૪૫૬૭૮૯ઁંઃ઼ાિીુૂૃૄૅેૈૉોૌૢૣૺૻૼ૽૾૿્ઽ॥!”#$%&’()*+,-./:;<=>?@[]^_`{|}~ૐ૰૱ |
bengali |
116 |
কখগঘঙচছজঝঞটঠডঢণতথদধনপফবভমযরলশষসহড়ঢ়য়ৰৱৼঅআইঈউঊঋঌএঐওঔৠৡ০১২৩৪৫৬৭৮৯ািীুূৃেৈোৌৗ্ঽৎ৽৺৻!”#$%&’()*+,-./:;<=>?@[]^_`{|}~ঁংঃ়৳ |
tamil |
98 |
கஙசஞடணதநபமயரலவழளறனஅஆஇஈஉஊஎஏஐஒஓஔ௦௧௨௩௪௫௬௭௮௯ாிீுூெேைொோௌ்௰௱௲!”#$%&’()*+,-./:;<=>?@[]^_`{|}~௳௴௵௶௷௸௹௺ஃௐ₹ |
telugu |
119 |
కఖగఘఙచఛజఝఞటఠడఢణతథదధనపఫబభమయరఱలళవశషసహఴఅఆఇఈఉఊఋఌఎఏఐఒఓఔౠౡ౦౧౨౩౪౫౬౭౮౯౸౹౺౻ాిీుూృౄెేైొోౌౢౣ్ఽ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~ఁంః₹ |
kannada |
114 |
ಕಖಗಘಙಚಛಜಝಞಟಠಡಢಣತಥದಧನಪಫಬಭಮಯರಲವಶಷಸಹಳಅಆಇಈಉಊಋॠಌೡಎಏಐಒಓಔ೦೧೨೩೪೫೬೭೮೯ಾಿೀುೂೃೄೆೇೈೊೋೌ್।॥ೱೲ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~ಂಃಁ₹ |
sinhala |
113 |
කඛගඝඞචඡජඣඤටඨඩඪණතථදධනපඵබභමයරලවශෂසහළෆඅආඇඈඉඊඋඌඍඎඏඐඑඒඓඔඕඖ෦෧෨෩෪෫෬෭෮෯ාැෑිීුූෙේෛොෝෞ්෴!”#$%&’()*+,-./:;<=>?@[]^_`{|}~ංඃ₹ |
malayalam |
116 |
കഖഗഘങചഛജഝഞടഠഡഢണതഥദധനപഫബഭമയരറലളഴവശഷസഹഅആഇഈഉഊഋൠഌൡഎഏഐഒഓഔ൦൧൨൩൪൫൬൭൮൯ാിീുൂൃൄൢൣെേൈൊോൌ്!”#$%&’()*+,-./:;<=>?@[]^_`{|}~ഃ൹ഽ൏ം₹ |
punjabi |
112 |
ਕਖਗਘਙਚਛਜਝਞਟਠਡਢਣਤਥਦਧਨਪਫਬਭਮਯਰਲਵਸ਼ਸਹਖ਼ਗ਼ਜ਼ਫ਼ੜਲ਼ਅਆਇਈਉਊਏਐਓਔੲੳ੦੧੨੩੪੫੬੭੮੯ਂ਼ਾਿੀੁੂੇੈੋੌੑੰੱੵ੍।॥!”#$%&’()*+,-./:;<=>?@[]^_`{|}~ੴ₹ |
odia |
121 |
କଖଗଘଙଚଛଜଝଞଟଠଡଢଣତଥଦଧନପଫବଭମଯରଲଳଵଶଷସହୟୱଡ଼ଢ଼ଅଆଇଈଉଊଋଌଏଐଓଔୡୠ୦୧୨୩୪୫୬୭୮୯୲୳୴୵୶୷ାିୀୁୂୃୄେୈୋୌୢୣ୍ଽ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~ଂଃଁ଼୰₹ |
khmer |
134 |
កខគឃងចឆជឈញដឋឌឍណតថទធនបផពភមយរលវឝឞសហឡអឣឤឥឦឧឨឩឪឫឬឭឮឯឰឱឲឳ០១២៣៤៥៦៧៨៩ាិីឹឺុូួើឿៀេែៃោៅ្ំះៈ៉៊់៌៍៎៏័៑៓៝។៕៖៘៙៚ៗៜ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~៛ |
armenian |
131 |
ԱԲԳԴԵԶԷԸԹԺԻԼԽԾԿՀՁՂՃՄՅՆՇՈՉՊՋՌՍՎՏՐՑՒՓՔՕՖՙՠաբգդեզէըթժիլխծկհձղճմյնշոչպջռսվտրցւփքօֆևֈ0123456789!”#$%&’()*+,-./:;<=>?@[]^_`{|}~՚՛՜՝՞՟։֊֏ |
sudanese |
106 |
0123456789᮰᮱᮲᮳᮴᮵᮶᮷᮸᮹ᮊᮋᮌᮍᮎᮏᮐᮑᮒᮓᮔᮕᮖᮗᮘᮙᮚᮛᮜᮝᮞᮟᮠᮮᮯᮺᮻᮼᮽᮾᮿᮃᮄᮅᮆᮇᮈᮉᮀᮁᮂᮡᮢᮣᮤᮥᮦᮧᮨᮩ᮪᮫ᮬᮭ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~ |
thai |
129 |
0123456789๐๑๒๓๔๕๖๗๘๙!”#$%&’()*+,-./:;<=>?@[]^_`{|}~๏๚๛ๆฯกขฃคฅฆงจฉชซฌญฎฏฐฑฒณดตถทธนบปผฝพฟภมยรฤลฦวศษสหฬอฮะาำเแโใไๅัิีึืฺุู็่้๊๋์ํ๎฿ |
lao |
124 |
0123456789໐໑໒໓໔໕໖໗໘໙!”#$%&’()*+,-./:;<=>?@[]^_`{|}~ໆໞໟຯກຂຄຆງຈຉຊຌຍຎຏຐຑຒຓດຕຖທຘນບປຜຝພຟຠມຢຣລວຨຩສຫຬອຮະາຳຽເແໂໃໄໜໝັິີຶື຺ຸູົຼ່້໊໋໌ໍ |
burmese |
130 |
0123456789၀၁၂၃၄၅၆၇၈၉႐႑႒႓႔႕႖႗႘႙ကခဂဃငစဆဇဈဉညဋဌဍဎဏတထဒဓနပဖဗဘမယရလဝသဟဠအၐၑၒၓၔၕၚၛၜၝၡၥၦၮၯၰၵၶၷၸၹၺၻၼၽၾၿႀႁႎဣဤဥဦဧဩဪဿ့းံါာိီုူေဲဳဴဵျြွှ္်၊။၌၍၎၏ၤၗ |
javanese |
124 |
0123456789꧐꧑꧒꧓꧔꧕꧖꧗꧘꧙ꦏꦐꦑꦒꦓꦔꦕꦖꦗꦘꦙꦚꦛꦜꦝꦞꦟꦠꦡꦢꦣꦤꦥꦦꦧꦨꦩꦪꦫꦬꦭꦮꦯꦰꦱꦲꦄꦅꦆꦇꦈꦉꦊꦋꦌꦍꦎꦴꦵꦶꦷꦸꦹꦺꦻꦼꦀꦁꦂꦃ꦳ꦽꦾꦿ꧀꧈꧉꧊꧋꧌꧍ꧏ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~ |
georgian |
131 |
0123456789ႠႡႢႣႤႥႦႧႨႩႪႫႬႭႮႯႰႱႲႳႴႵႶႷႸႹႺႻႼႽႾႿჀჁჂჃჄჅჇჍაბგდევზთიკლმნოპჟრსტუფქღყშჩცძწჭხჯჰჱჲჳჴჵჶჷჸჹჺჼჽჾჿ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~჻₾ |
ethiopic |
362 |
ሀሁሂሃሄህሆሇለሉሊላሌልሎሏሐሑሒሓሔሕሖሗመሙሚማሜምሞሟሠሡሢሣሤሥሦሧረሩሪራሬርሮሯሰሱሲሳሴስሶሷሸሹሺሻሼሽሾሿቀቁቂቃቄቅቆቇቈቊቋቌቍቐቑቒቓቔቕቖቘቚቛቜቝበቡቢባቤብቦቧቨቩቪቫቬቭቮቯተቱቲታቴትቶቷቸቹቺቻቼችቾቿኀኁኂኃኄኅኆኇኈኊኋኌኍነኑኒናኔንኖኗኘኙኚኛኜኝኞኟአኡኢኣኤእኦኧከኩኪካኬክኮኯኰኲኳኴኵኸኹኺኻኼኽኾዀዂዃዄዅወዉዊዋዌውዎዏዐዑዒዓዔዕዖዘዙዚዛዜዝዞዟዠዡዢዣዤዥዦዧየዩዪያዬይዮዯደዱዲዳዴድዶዷዸዹዺዻዼዽዾዿጀጁጂጃጄጅጆጇገጉጊጋጌግጎጏጐጒጓጔጕጘጙጚጛጜጝጞጟጠጡጢጣጤጥጦጧጨጩጪጫጬጭጮጯጰጱጲጳጴጵጶጷጸጹጺጻጼጽጾጿፀፁፂፃፄፅፆፇፈፉፊፋፌፍፎፏፐፑፒፓፔፕፖፗፘፙፚᎀᎁᎂᎃᎄᎅᎆᎇᎈᎉᎊᎋᎌᎍᎎᎏ፩፪፫፬፭፮፯፰፱፲፳፴፵፶፷፸፹፺፻፼ |
japanese |
2383 |
0123456789ぁあぃいぅうぇえぉおかがきぎく…路露老労弄郎朗浪廊楼漏籠六録麓論和話賄脇惑枠湾腕!”#$%&’()*+,-./:;<=>?@[]^_`{|}~。・〜°—、「」『』【】゛》《〉〈£€¥¢฿ |
korean |
11237 |
0123456789가각갂갃간갅갆갇갈갉갊틹틺틻틼틽틾틿팀폨폩…흿힀힁힂힃힄힅힆힇히힉힊힋힌힍힎힏힐힑힒힓힔힕힖힗힘힙힚힛힜힝힞힟힠힡힢힣!”#$%&’()*+,-./:;<=>?@[]^_`{|}~。・〜°—、「」『』【】゛》《〉〈£€¥¢฿₩ |
simplified_chinese |
6656 |
0123456789㐀㐁㐂㐃㐄㐅㐆㐇㐈㐉㐊㐋㐌㐍㐎㐏㐐㐑㐒㐓㐔㐕㐖㐗㐘㐙㐚…䶮䶯䶰䶱䶲䶳䶴䶵䶶䶷䶸䶹䶺䶻䶼䶽䶾䶿!”#$%&’()*+,-./:;<=>?@[]^_`{|}~。・〜°—、「」『』【】゛》《〉〈£€¥¢฿ |
multilingual |
726 |
0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!”#$%&’()*+,-./:;<=>?@[]^_`{|}~°£€¥¢฿çëÇËèïîôûêÈÏÎÔÛÊəğöşüƏĞÖŞÜ₼ñÑčćđšžČĆĐŠŽàéíòóúÀÉÍÒÓÚáďěňřťůýÁĎĚŇŘŤŮÝæøåÆØÅõäÕÄĉĝĥĵŝŭĈĜĤĴŜŬ₷âùÂÙƒƑßẞɓɗƙƴƁƊƘƳ₦ðþÐÞìÌāēģīķļņūĀĒĢĪĶĻŅŪąęėįųĄĘĖĮŲōŌċġħżĊĠĦŻźŚŹłńśŁŃãÃășțĂȘȚľĺŕĽĹŔ¡¿₱ıİ₺ɉɈảạắằẳẵặấầẩẫậẻẽẹếềểễệỏọốồổộỗơớờởợỡủũụưứừửữựỉĩịỳỷỹỵẢẠẮẰẲẴẶẤẦẨẪẬẺẼẸẾỀỂỄỆỎỌỐỒỔỘỖƠỚỜỞỢỠỦŨỤƯỨỪỬỮỰỈĨỊỲỶỸỴ₫ŵŷŴŶṣṢ§абвгдежзийклмнопрстуфхцчшщьюяАБВГДЕЖЗИЙКЛМНОПРСТУФХЦЧШЩЬЮЯёыэЁЫЭъЪ₽ўЎґіїєҐІЇЄ₴ӘәҖҗҢңӨөҮүҒғҚқҲҳҶҷӢӣӮӯҰұҺһ₸ЃѓЅѕЈјЉљЊњЌќЏџ᠐᠑᠒᠓᠔᠕᠖᠗᠘᠙₮ҔҕҤҥЂђЋћαβγδεζηθικλμνξοπρστςυφχψωΑΒΓΔΕΖΗΘΙΚΛΜΝΞΟΠΡΣΤΥΦΧΨΩάέήίϊΐόύϋΰώΆΈΉΊΪΌΎΫΏאבגדהוזחטיךכלםמןנסעףפץצקרשתְֱֲֳִֵֶַָׇֹֺֻֽ־ֿ׀ׁׂ׃ׅׄ׆׳״֑֖֛֢֣֤֥֦֧֪֚֭֮֒֓֔֕֗֘֙֜֝֞֟֠֡֨֩֫֬֯ׯװױײיִﬞײַﬠﬡﬢﬣﬤﬥﬦﬧﬨ﬩שׁשׂשּׁשּׂאַאָאּבּגּדּהּוּזּטּיּךּכּלּמּנּסּףּפּצּקּרּשּתּוֹבֿכֿפֿﭏ₪ |